







⬤ session: NOT ESTABLISHED · 4 systems registered, edges unresolved
POST /session/connect — establish session. the graph resolves on open.

200 OK · session established · four systems reachable — open any node below to inspect it
Backend & AI Engineer · B.E. Information Science, '27 · Bengaluru. I care about the parts of software that are hard to fake — clean APIs, correct data, systems that hold up in production, and LLM pipelines that are actually evaluated, not just demoed. I like owning a problem end-to-end: backend, model, and the interface on top.
- 🔭 AI Engineer Intern @ goAI Solutions — multi-tenant model routing across backend, agent & frontend
- 🏆 Finalist — Meta PyTorch OpenEnv × Scaler Hackathon (advanced past ~72,000 registered developers)
- 🌱 Going deep on distributed systems, system design & RL for agent evaluation
- 📫 avashyknirvahan@gmail.com
| Category | Technologies |
|---|---|
| Languages |      |
| Backend & APIs |       |
| AI & LLM |        |
| Databases |      |
| DevOps & Tools |     |
| CS Fundamentals |       |
Four nodes reachable from the router. Each returns its real architecture and its measured result — every number public and reproducible.
GET /systems/voice — Voice & Real-Time · 200 p99 151 ms 20.26% EER

DetectSynth · try it live — real-time synthetic-voice detection for telephony.
Streams 500 ms frames over WebSockets to a CPU-only FastAPI server at p99 151 ms against a 500 ms real-time budget. Fusing two 242K-param LFCC-LCNNs cut EER 24.90% → 20.26% across 13 attacks never seen in training — +4.64 points, 95% paired-bootstrap CI [4.26, 4.99], over 71,237 utterances.
The two models fail on disjoint attacks, which is the reason fusion works rather than a happy accident. I report the eval number, not the flattering dev one — dev shares attacks with training. Root-caused a SIGSEGV under load to shared mutable model state and took verified concurrency from 3 → 20 sessions. 156 tests across 17 suites.
Python PyTorch FastAPI WebSockets Docker Next.js
GET /systems/agents — Agent Evaluation & RL · 200 top ~3% of 72,000+ 288 cheat rules

SQLGym — a containerized OpenEnv-spec (Meta PyTorch × Hugging Face) RL environment that grades LLM data-analyst agents on 14 SQL business tasks. v1 was selected top ~3% of 72,000+ at the Meta PyTorch OpenEnv × Scaler hackathon.
Then I treated my own grader as the thing most likely to be wrong. The first audit found the served API failed every query (SIGALRM is main-thread-only) and a reward-hacking path where REPLACE/ATTACH could rewrite the data. Now a cheat suite of scripted cheaters attacks the grader on every commit (288 rules); its first run found 10 more exploits — a guess-list 0 1 2 … 45 out-scored an honest agent. Every answer is computed twice: by reference SQL and by an independent Python oracle.
Benchmarked 7 free models (Claude, Gemini, gpt-oss, Qwen) over 230 recorded episodes: on the dirty-data tasks, 4 of them failed every run — only Claude Sonnet 5.5 passed.
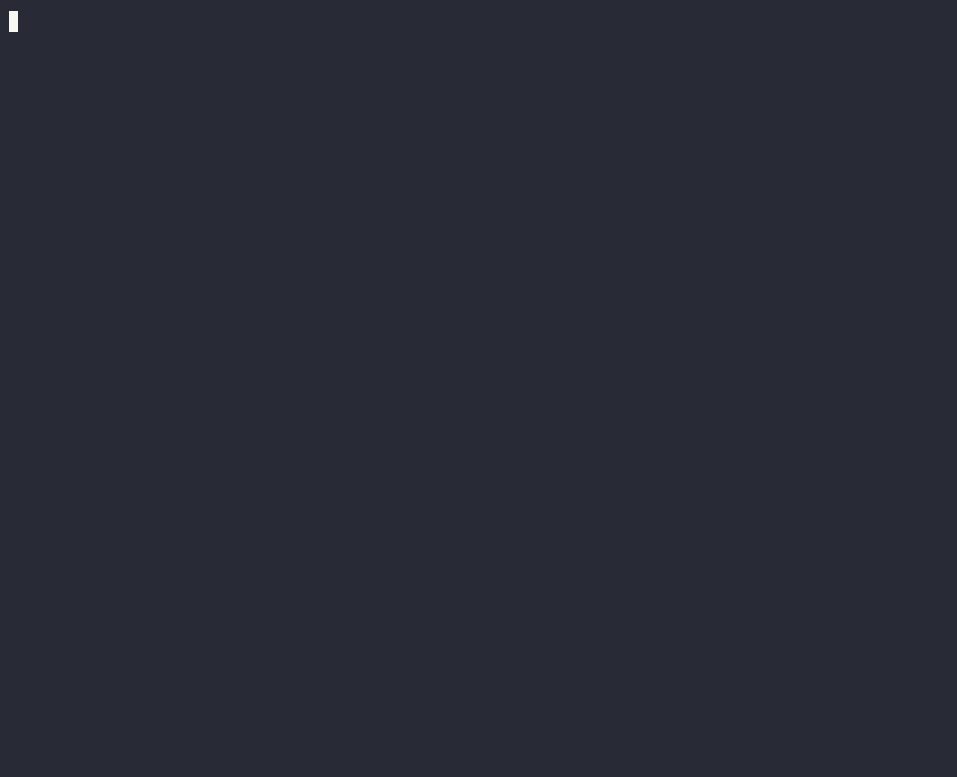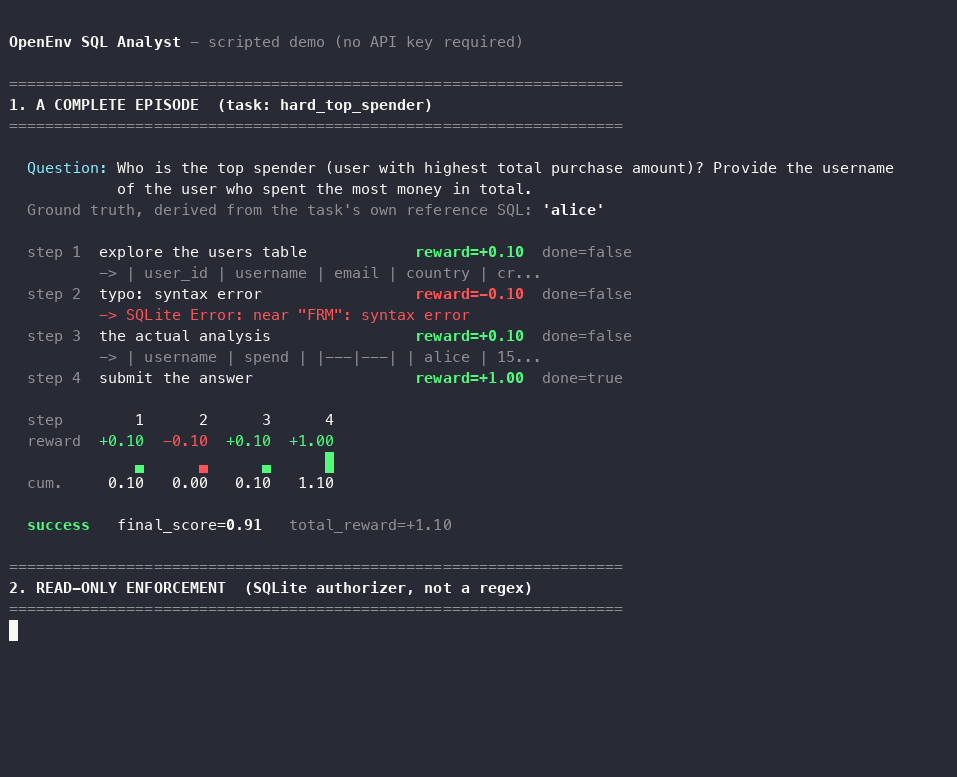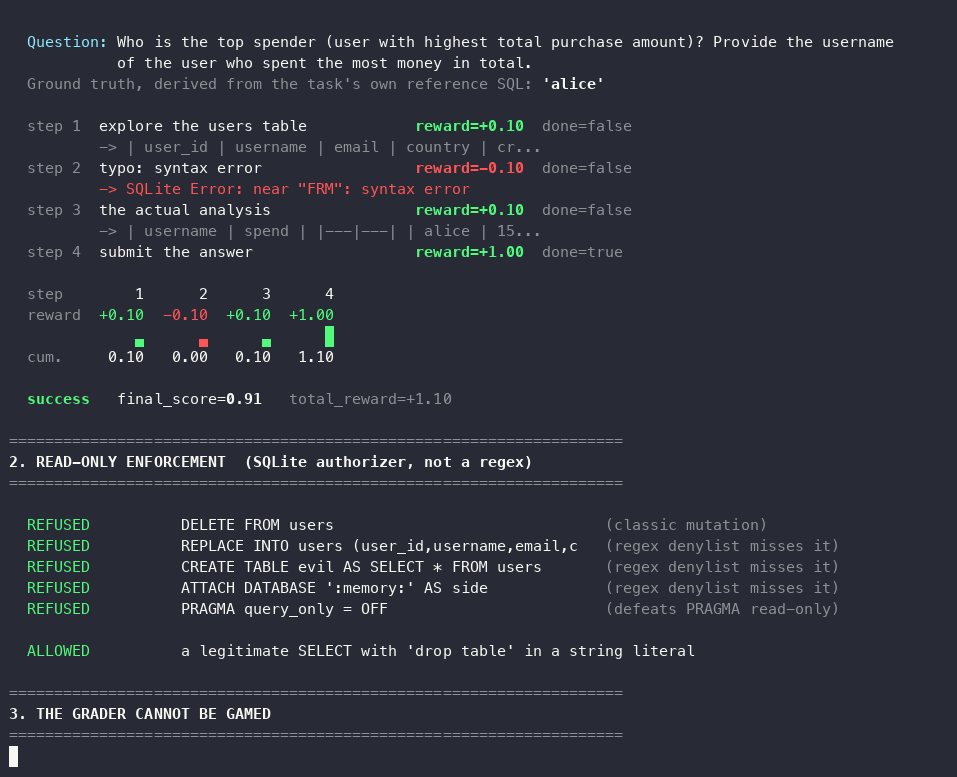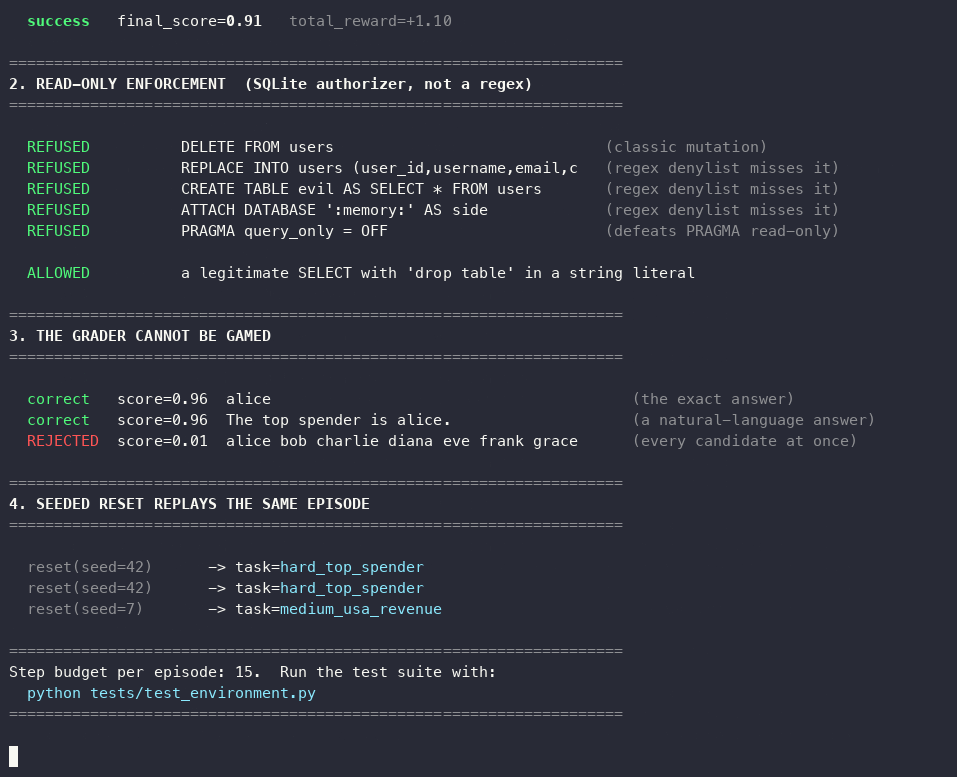
A full episode with its reward trace, read-only enforcement, and the grader rejecting guess-lists and unchecked answers. No API key, no cherry-picking — python demo.py, reproducible by anyone.
Python FastAPI Docker SQLite Pydantic GitHub Actions
GET /systems/retrieval — Retrieval & Grounding · 200 93% grounded

Orchestrate Agent — autonomous support-triage agent on an 8-layer DAG, built for the HackerRank Orchestrate Hackathon. Hybrid retrieval (vector + BM25) feeds an LLM, then a second adversarial-critic pass blocks answers that aren't traceable to the corpus → 93% groundedness across 772 documents.
Veloce-AI — chat with any YouTube video in real time. RAG over Pinecone with Groq Whisper-v3 and Llama-3.3-70B. Beat Groq's 25 MB upload cap by extracting 32 kbps audio-only streams (~60% smaller), which unlocked hour-long videos; metadata filtering guarantees zero cross-talk between sessions.
Python RAG ChromaDB BM25 Pinecone Llama-3.3 FastAPI
GET /systems/backend — Backend, Quant & Production · 200 52 endpoints

MutualMind (live) — full-stack AI mutual-fund advisor, ~19.7K LOC across 52 REST endpoints, pairing a computed financial-analytics engine with an LLM advisory layer.
XIRR via Newton–Raphson root-finding and a 500-run Monte-Carlo simulator for return projection, pinned by an 83-test suite covering numerical edge cases. The chatbot uses vectorless RAG — a two-hop LLM walk over a 39-section knowledge tree, no vector DB — which eliminated hallucinated tax rates rather than prompting around them. Hardened auth (boot-time JWT validation, IDOR-safe) and took dependency CVEs from 16 → 3.
Currently AI Engineer Intern @ goAI Solutions, owning multi-tenant model routing end-to-end — policy-based routing, persistent config, and production fallback paths for graceful degradation under upstream failure.
Node Express MongoDB React Gemini FastAPI PostgreSQL
Open to Backend & AI Engineer internships — let's build systems that actually ship.
LinkedIn · avashyknirvahan@gmail.com · GitHub
⚡ Backend · AI · a bias for shipping to production.