Repository navigation
A wrong_translation report runs the validator - #916
Merged
Merged
Conversation


Roadmap 0c, step 2. The validator judges the reported word in the sentence
the learner saw it in, even when the meaning was already VALID (a VALID
meaning is otherwise never looked at again). It runs in the background;
its verdict (valid / fixed / invalid / gave_up / not_judged) and the
validation_log row go on the report. A FIX does what it does anywhere:
the learner moves to the corrected meaning, the old one is INVALID.

tools/judge_word_reports.py judges the reports without a verdict: the 14
from before, and any the validator didn't answer.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

|
ArchLens detected architectural changes in the following views: |
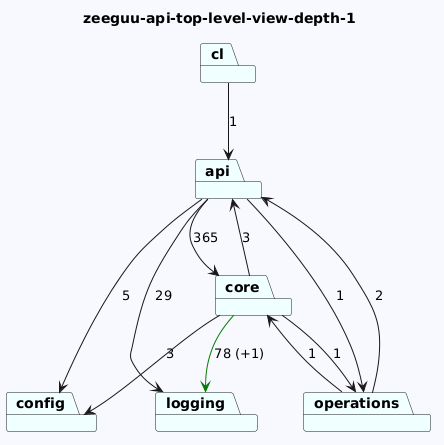
The learner's word is skipped on report anyway, so judging right away only
fixes the meaning for others a few hours sooner, at the cost of a thread per
report and a race with the skip. tools/judge_word_reports.py --apply runs from
the ops crontab instead.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment

Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
Roadmap 0c, step 2. Follows #914.
What happens on a report
tools/judge_word_reports.py --apply(ops crontab, 05:20) runs the validator on thewrong_translationreports without a verdict: from exercises, from the reader's "wrong meaning", and from "bad translation" in the remove dialog. The endpoints only file the report; the learner's word is skipped at once anyway.vil sige = meanandbud = bidstayed.not_judgedwhen there is no sentence, or when the word has already moved to another meaning.outcome(valid / fixed / invalid / gave_up / not_judged),validation_log_idandjudged_at.judged_atstays empty and the next night's run tries again.validate_and_fixgets two optional arguments:bookmark(the sentence to judge in) andrecheck(judge even a VALID meaning). Both are passed on when it moves to another sentence.Deploy
26-10-25-c--word_report_outcome.sql: adds 3 columns to a 47-row table.tools/judge_word_reports.pywithout--applylists the 14 oldwrong_translationreports it will judge. Judging costs a few cents and may change meanings for everyone.Tests pass; the judge tests use a fake validator, so they never call the LLM.
🤖 Generated with Claude Code